- Minimum Requirements
- Install Crusco Agentic Content
- Enable Updates
- Activate Pro Features
- Welcoming AI Bots with Agent Readability
- Guiding LLMs with YAML Front Matter
- Define AI Policy
- Creating perfect Markdown
- View the Markdown served to the AI
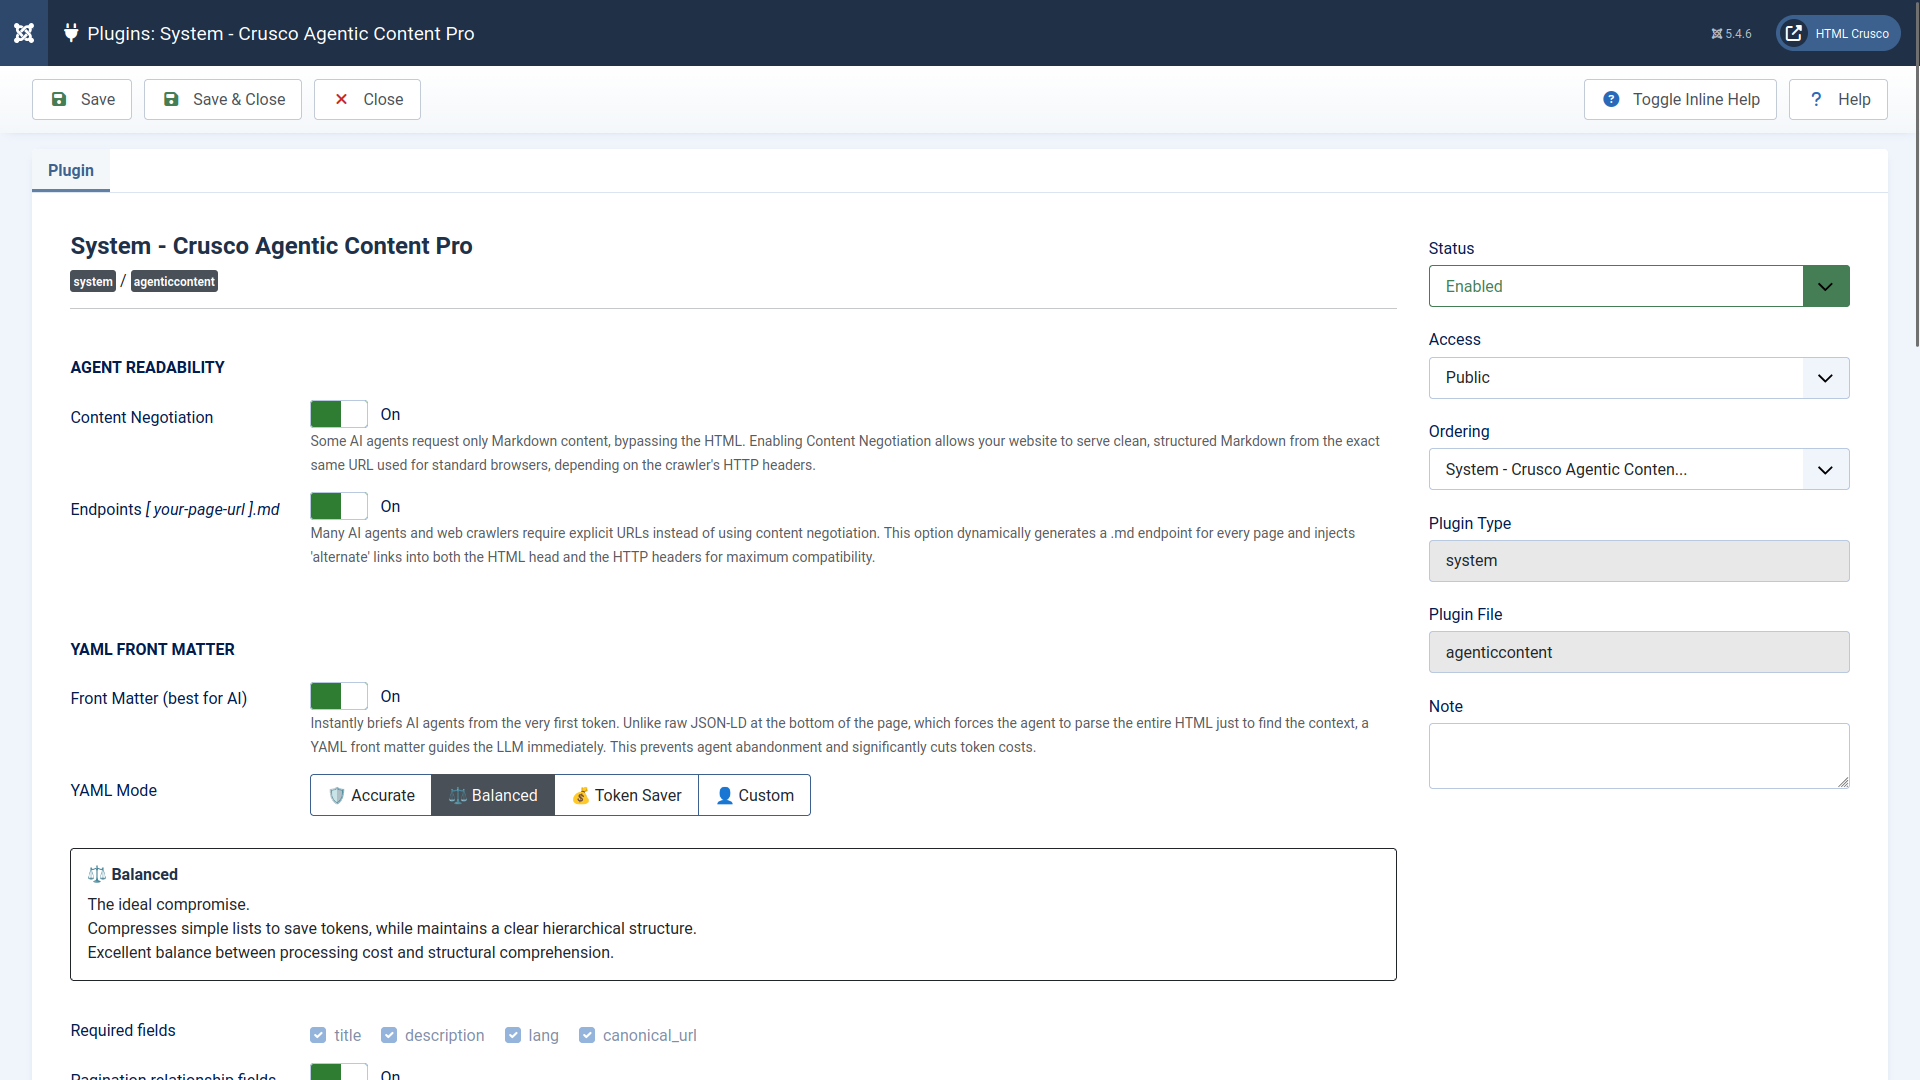
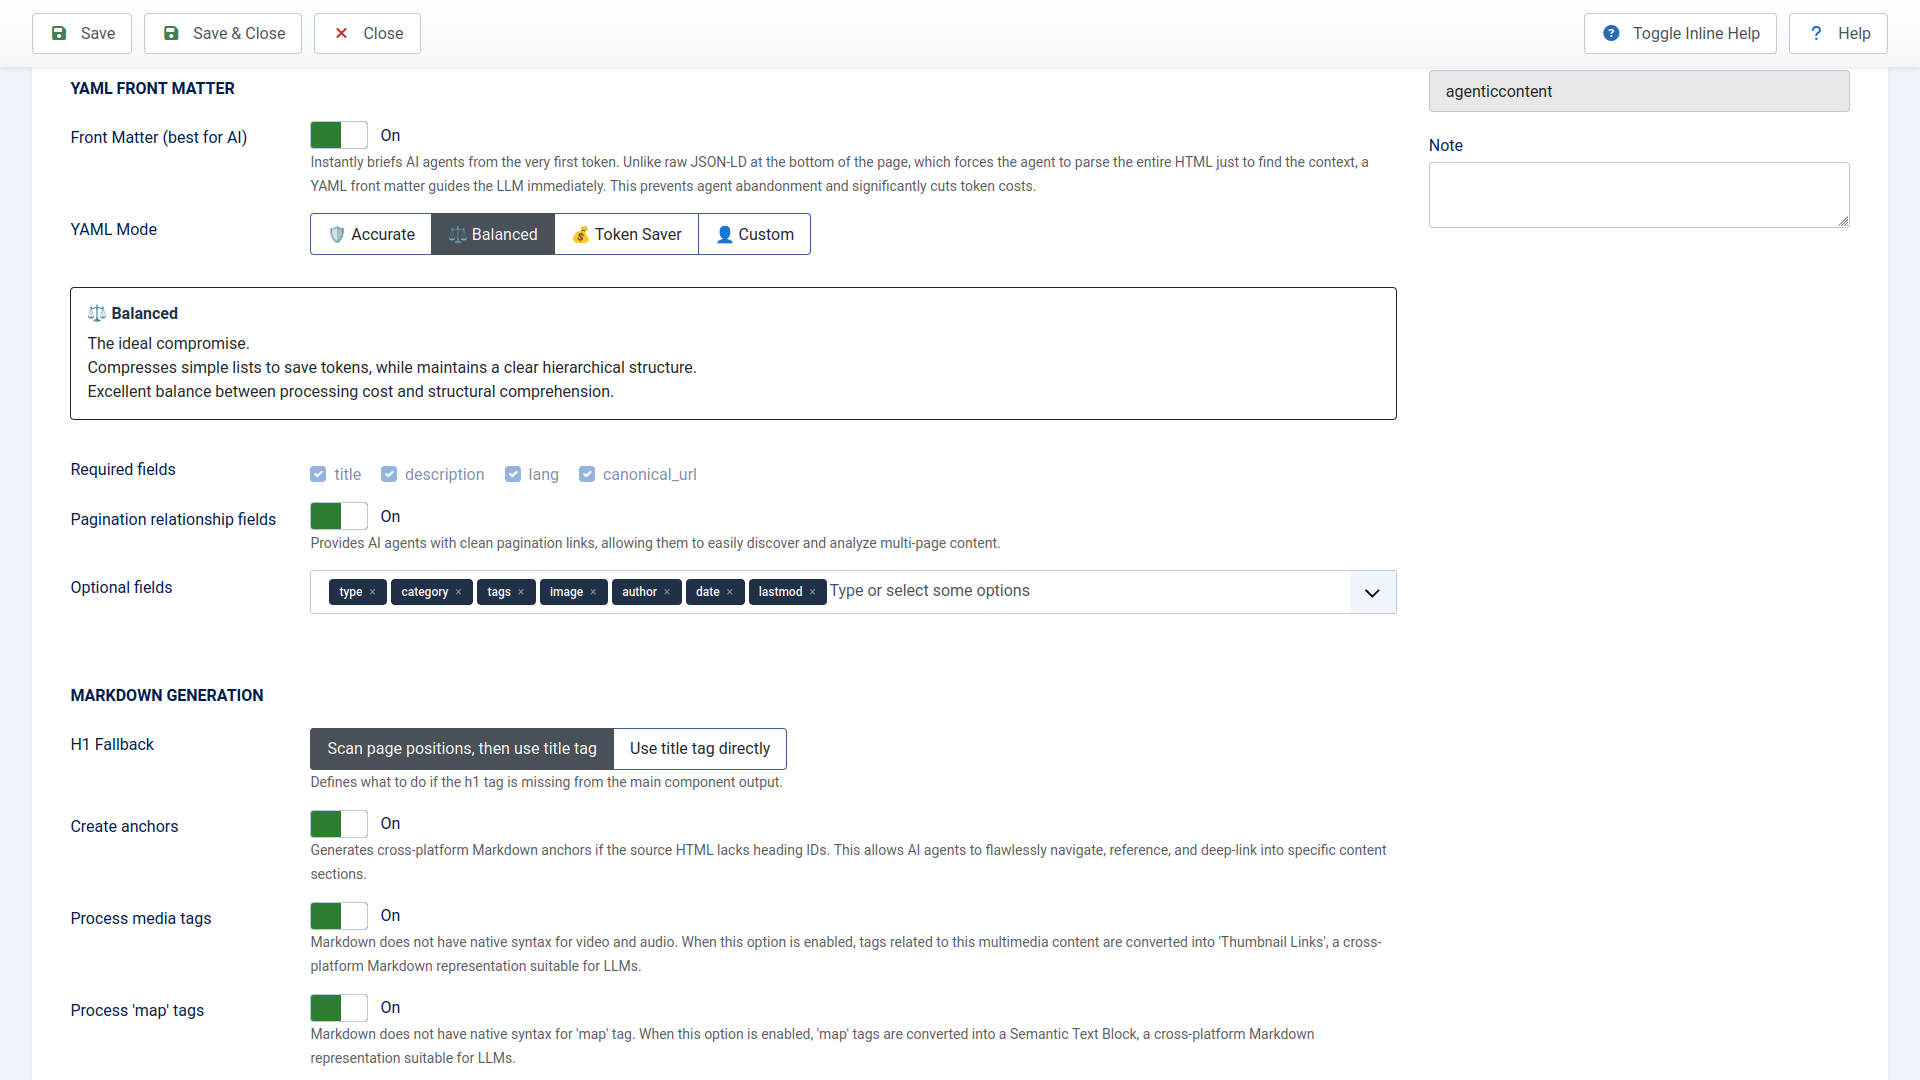
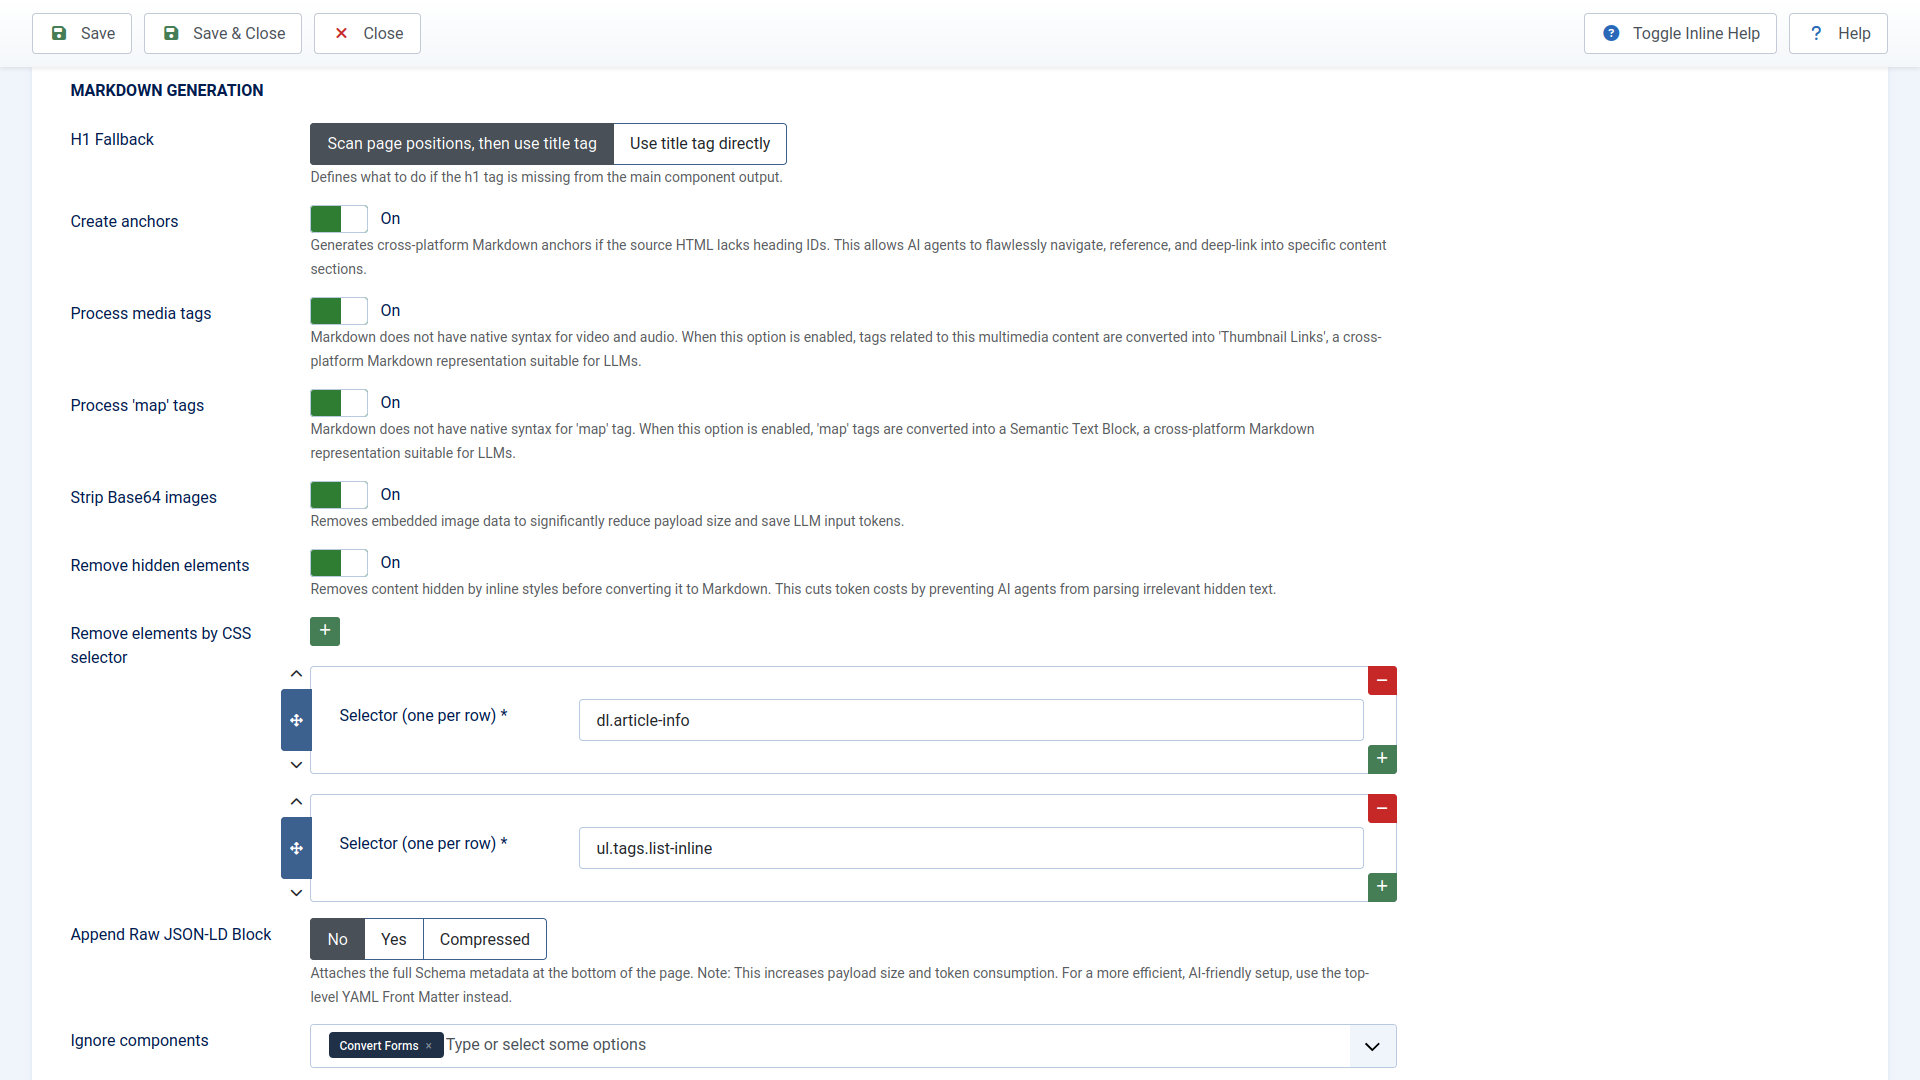
- Plugin screenshots
Minimum requirements
The extension is compatible with Joomla! 5 and Joomla! 6.
The minimum requirements match those of the respective Joomla versions, which you can review in the official documentation.
Install Crusco Agentic Content
Get the installation package from the download section of your account and upload it to Joomla:
System -> Extensions -> Install Extensions
Once the installation is complete, go back to System -> Extensions and enable:
- System - Crusco Agentic Content
Enable updates
To receive updates:
- Note down your Download ID
- In Joomla, go to System -> Update Sites -> Crusco Agentic Content
- Enter your Download ID in the Download Key field.
If you experience update issues after upgrading from the Free plan to one of the Pro plans, navigate to:
System -> Update Sites -> Rebuild
Activate Pro features
If you have installed the Free version of Crusco Agentic Content and later upgraded to a Personal, Professional or Agency plan, follow these steps to activate the Pro features:
- Download the "Pro" package of the plugin from the download section of your account.
- Upload it to Joomla via System -> Extensions -> Install Extensions
- Go to System -> Plugins -> System - Crusco Agentic Content Pro and configure the new features you need.
Welcoming AI Bots with Agent Readability
Artificial Intelligence-based search engines work natively with the Markdown format.
When an AI bot reads an HTML page, it encounters layout code, menus, sidebars, footers, and scripts. To extract useful text, it must perform a costly parsing process that risks fragmenting the information or compromising the original meaning of the text.
Providing the bot with a Markdown version of your content ensures better text comprehension and, consequently, much more accurate citations and answers.
To avoid any risk of SEO cannibalization or duplicate content, Crusco Agentic Content automatically instructs traditional search engines (such as Google) not to index the Markdown version of your pages.
This setup ensures your primary HTML pages retain full ranking priority in traditional SERPs, while Google and AI crawlers safely digest the frictionless Markdown version to generate accurate citations inside Google AI Overviews and AI Search responses.
For Markdown to be properly served to every AI crawler (a crawler is a type of bot dedicated to scanning), your Joomla site must expose it through two methods that have become the de facto standard:
- Content Negotiation
- Markdown alternate
You can activate both to ensure full compatibility with every AI crawler. In both modes, Crusco Agentic Content will serve the Markdown while respecting the HTTP security headers defined for your Joomla site, such as Strict-Transport-Security (HSTS) and Content-Security-Policy (CSP).
Content Negotiation
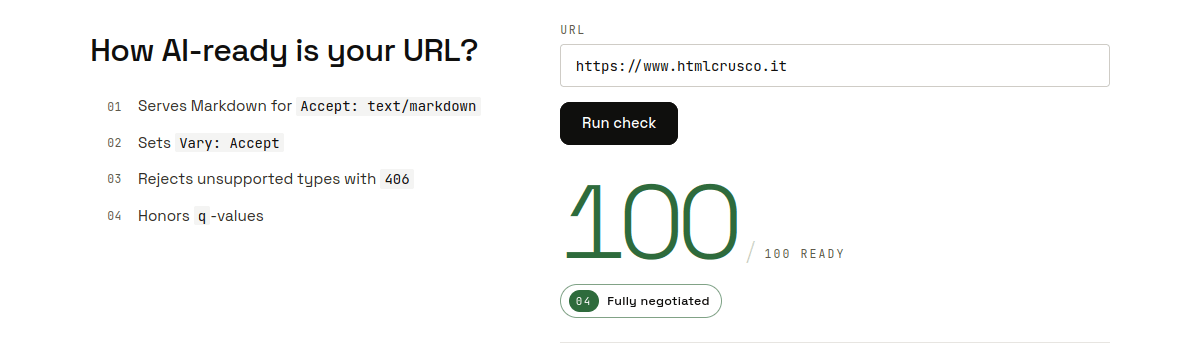
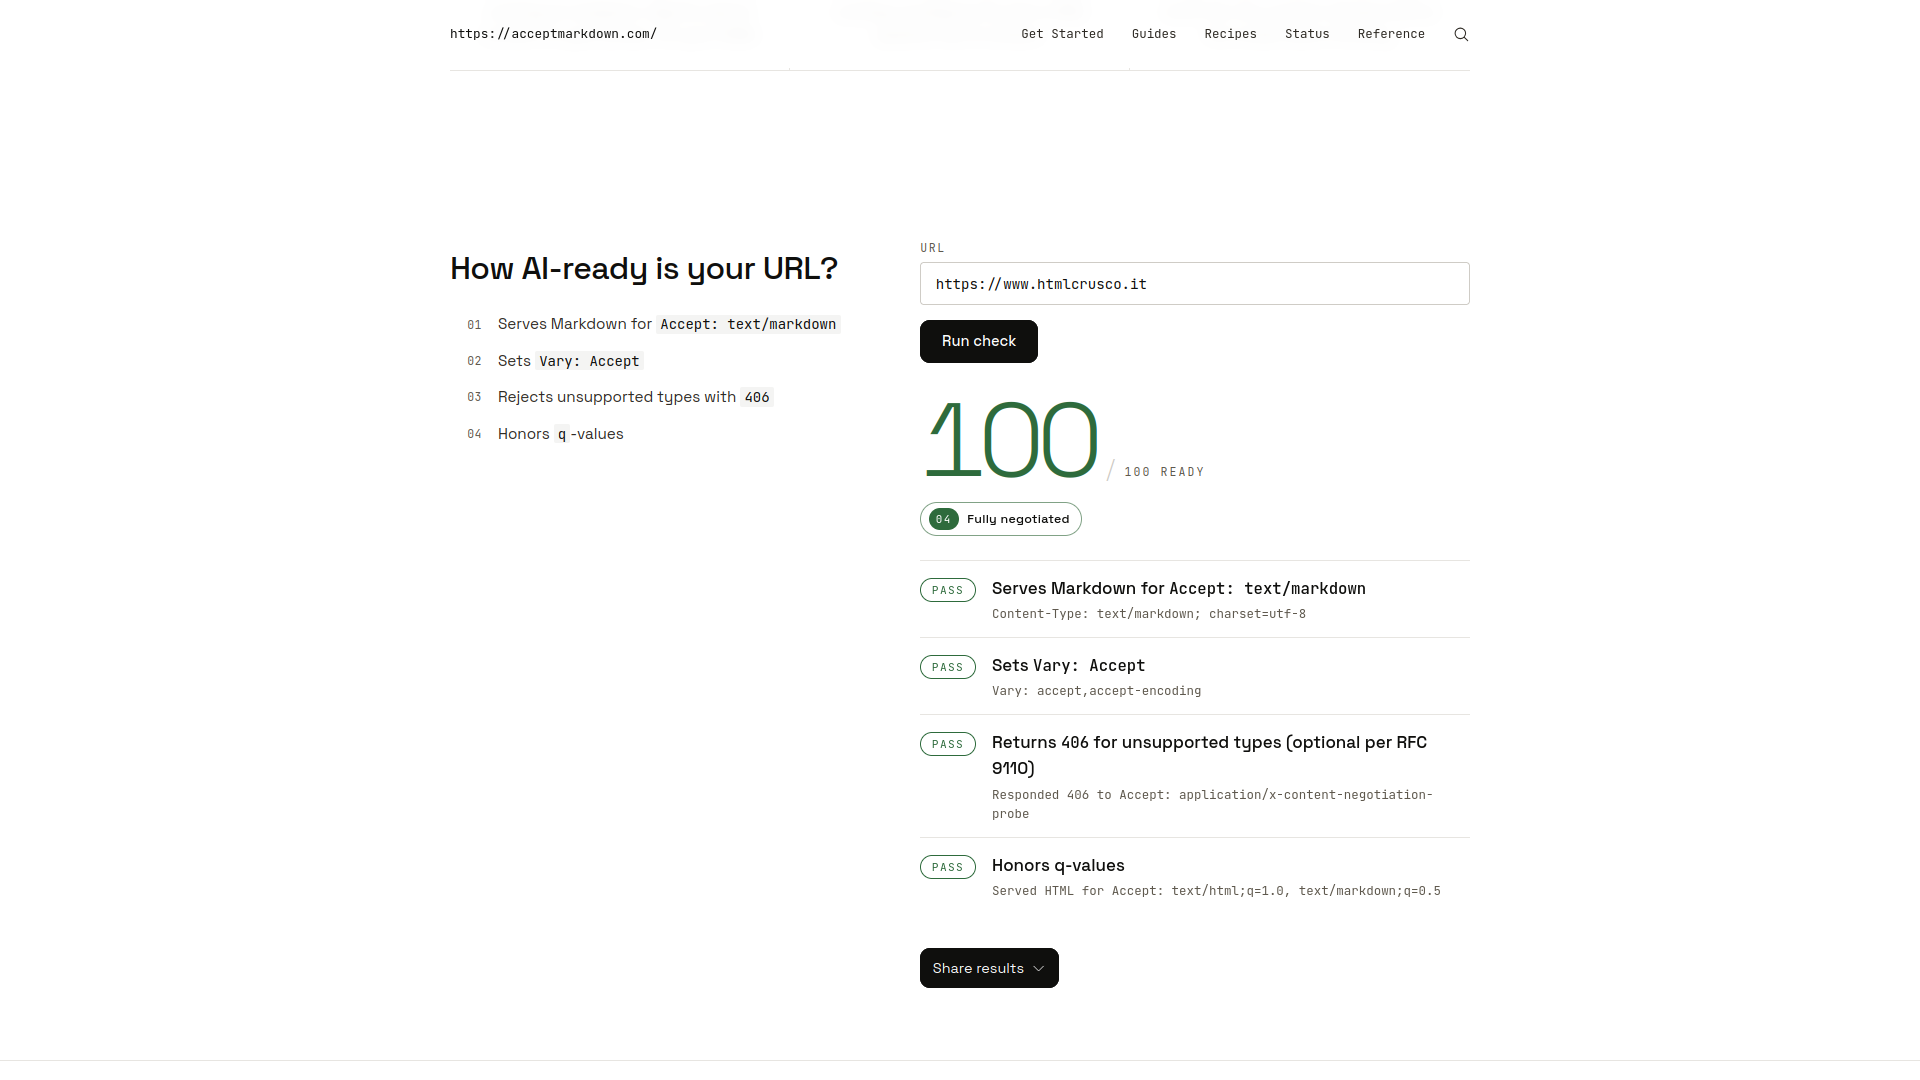
Content Negotiation is the HTTP mechanism that allows a server to serve different representation formats of a resource from the exact same URL. The server chooses which format to send based on the client's Accept header.
Users (via browsers) request HTML code complete with navigation elements, CSS, and scripts. Conversely, LLM agents require clean text, free of interface elements and "clutter" that distracts them from the actual value of the content.
With this option enabled, Crusco Agentic Content activates Content Negotiation following the rules defined in RFC 9110: your site will continue to display pages in HTML format to users, but it will automatically convert them into Markdown format so that they can be served to AI search engine crawlers that require it.
Furthermore, to prevent CDN caching issues and ensure secure delivery, the plugin sets the correct HTTP headers for every negotiated response.
Markdown alternate
While Content Negotiation operates "behind the scenes" on the same URL, the Markdown alternate is a public URL dedicated to the Markdown format version of the page (for example, https://yoursite.com/your-page.md or https://yoursite.com/your-page?markdown=1).
To ensure maximum compatibility and rapid bot discovery, Crusco Agentic Content complies with the RFC 8288 standard. It embeds the link to the alternative URL both as a <link> tag within the page's HTML code and inside its HTTP header. This allows crawlers to instantly detect the Markdown URL using any scanning method.
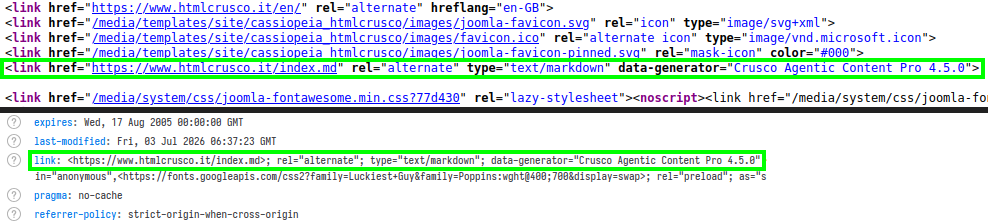
Bot behavior analysis shows that crawlers do not all act the same way: some negotiate the format within the same address, while others prefer to actively look for references to an external Markdown file.
By enabling this option, you ensure full compatibility with all AI bots that prefer to discover and navigate Markdown content through direct URLs.
Want to see how different AI agents discover Markdown content?
Check out the full breakdown in:
Guiding LLMs with YAML Front Matter
Large Language Models (LLMs) interpret content with much higher accuracy when the context and page metadata are explicitly declared in the very first lines. By enabling the “Front Matter” option, Crusco Agentic Content optimizes the initial scan by placing a YAML Front Matter block at the top of every Markdown file.
While JSON-LD remains the benchmark standard for traditional search engines (such as Google), Large Language Models process YAML natively and far more efficiently.
Integrating YAML Front Matter offers two strategic benefits:
- Native Parsing and Token Optimization: YAML minimizes syntactic "noise" by eliminating the curly braces, quotation marks, and nested formatting typical of JSON-LD, resulting in drastic token savings. Within just a few lines, the plugin encloses the author's identity (crucial for E-E-A-T criteria), the schema type, content freshness, and Joomla taxonomies, allowing models to digest the data instantly.
- Semantic Routing for RAG Systems: Clean metadata optimizes semantic routing processes within RAG architectures. It enables AI agents to filter, catalog, and validate the source on the spot, determining its authority and relevance before text chunking even begins.
With this option enabled, Crusco Agentic Content provides every Markdown resource with a true semantic identity document, maximizing how effectively your Joomla site is read, indexed, and cited by modern AI search engines.
YAML Mode
When the “Front Matter” option is enabled, Crusco Agentic Content provides four formatting modes for the YAML Front Matter—three presets and one custom option:
- 🛡️ Accurate:
Maximum precision. Fully expanded structure. It minimizes the risk of AI hallucinations by providing a clear separation between each individual data point. This is the safest choice for complex data.
- ⚖️ Balanced:
The ideal compromise. It compresses simple lists to save tokens while maintaining a clear hierarchical structure. It offers an excellent balance between processing costs and structural comprehension.
- 💰 Token Saver:
High data volumes / Reduced budget. Maximum data density for minimal token consumption. Recommended only for linear content, as the extreme density can increase the risk of parsing omissions or AI hallucinations.
- 👤 Custom:
User-defined. You decide how the YAML is dumped. Choose this mode if you want full control over the Front Matter formatting by configuring the following parameters:
- Inline: The hierarchical depth level where the output switches to inline YAML.
- Indent: The number of spaces to use for nesting nodes.
Required fields
These are the essential fields included in every standard YAML Front Matter block, all automatically populated by the plugin.
title: The title of the content. It corresponds to the HTMLh1tag and replaces the Heading 1 (#) in the Markdown. According to the specification when a Front Matter block containing thetitlefield, Heading 1 (#) must not be present in the Markdown body.description: The summary of the content, corresponding to the meta description tag so vital for SEO.lang: Crucial for instantly classifying the content language (e.g., it-IT, en-GB).canonical_url: The URL that will appear in the "sources" list when LLMs answer prompts. Ideally, it matches the URL in the thelink rel="canonical"tag; if that tag is missing, the plugin falls back to the HTML page URL.
Pagination relationship fields
This option instructs AI systems on how to correctly navigate multi-page content (e.g., category article lists or articles split across multiple pages).
If the original HTML page correctly includes the pagination relationship values rel="next" and rel="prev", Crusco Agentic Content uses them to generate the next and prev fields within the Front Matter.
If your site doesn't manage these tags correctly, consider using our professional plugin for comprehensive canonical management and advanced negative SEO protection for Joomla. It integrates seamlessly with Crusco Agentic Content:
Optional fields
Crusco Agentic Content allows you to automatically insert additional information into the YAML Front Matter to help language models correctly classify and cite your content.
type: The general semantic classification of the content. It is extracted by parsing the Schema Markup of the HTML page. The recognized and supported types are:- AdvertiserContentArticle
- Article
- Blog
- BlogPosting
- Book
- ComicStory
- Course
- CreativeWork
- Diet
- DiscussionForumPosting
- Event
- Guide
- HowTo
- JobPosting
- MobileApplication
- NewsArticle
- Product
- Recipe
- Report
- SatiricalArticle
- ScholarlyArticle
- SocialMediaPosting
- SoftwareApplication
- TechArticle
- Thesis
- VideoGame
- WebApplication
- WebPage
categoryandtags: Joomla taxonomies that clarify the content context.dateandlastmod: Publication date and last modification date of the content, indicating its chronological freshness.image: The path to the representative image of the content, which LLMs can use in citations. The plugin prioritizes the intro image; if unavailable, it selects the full article image.author: Used by LLMs as a criterion to evaluate the quality of the content and the author (or the site in general). By default, it contains the name of the article's author. However, if the Schema Markup of the HTML page contains additional author data, it is also extracted and included in the Front Matter to boost E-E-A-T.For this reason, it is recommended to provide at least the following details for the author:
- Full Name
- Photo
- Profession
- A brief biography
- Link to personal website/blog
- Links to social media profiles.
If you don't know how to easily add an author biography to your content, we recommend checking out our extension for creating professional author profiles in Joomla. It fully supports Schema Markup and pairs exceptionally well with Crusco Agentic Content:
Defining AI Policy
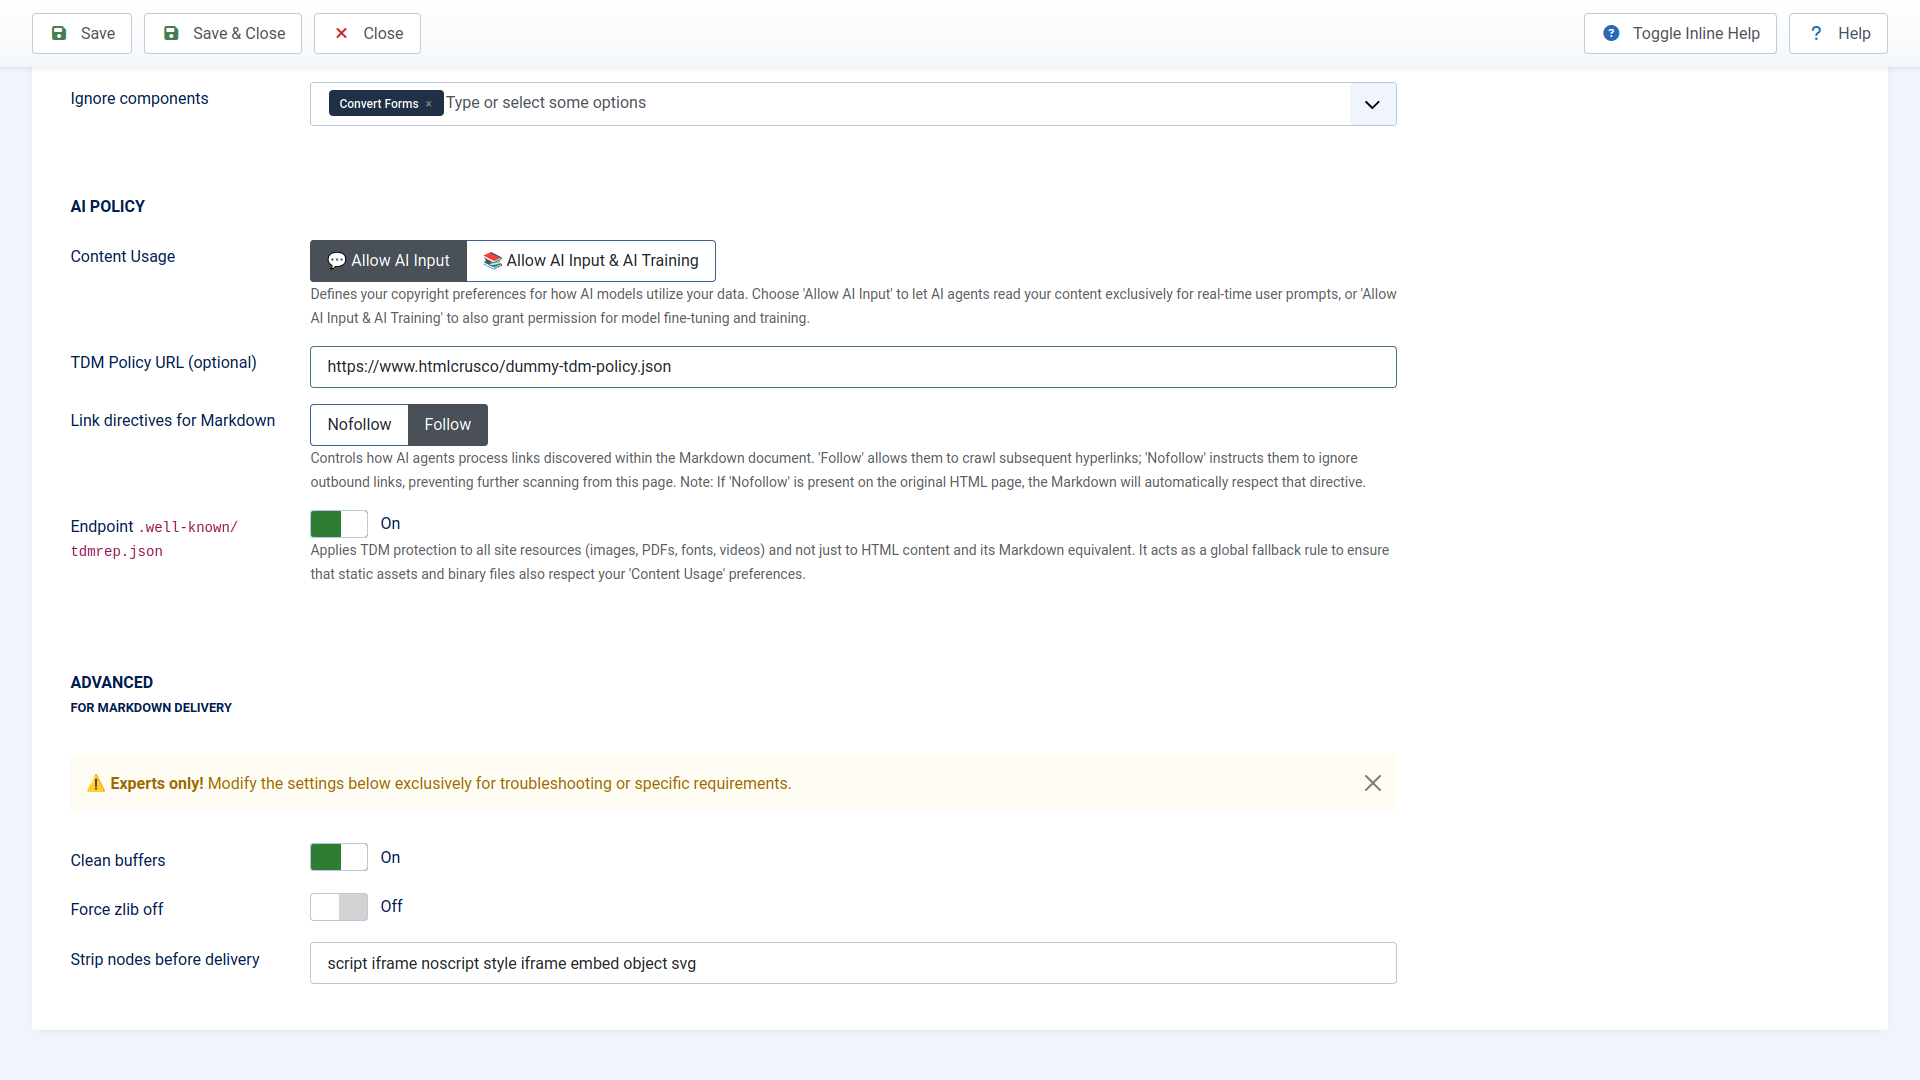
The use of data by language models is at the heart of the copyright debate. Through the AI Policy section of Crusco Agentic Content, you regain control over your content by setting clear rules directly within the HTTP headers of the responses generated by your site.
Content Usage
This option allows you to define the protection level of your texts in full compliance with Article 53 of the EU AI Act, which legally binds AI providers to respect copyright reservations expressed through machine-readable means.
To guarantee maximum security, the plugin simultaneously activates two different global standards: the TDMRep protocol, the official standard ratified by the W3C for European copyright protection, and the Content Signals syntax (an open initiative promoted by Cloudflare and Thoughtworks, currently under discussion at the IETF for official ratification, but already a de facto standard adopted and respected by major global crawlers).
By choosing between the two available modes, you automatically configure access for bots:
- Allow AI Input: This instructs AI systems (such as Perplexity or ChatGPT Search) that they may read your pages exclusively to provide real-time answers to immediate user queries (RAG systems). At the same time, it categorically prohibits the ingestion, scraping, and storage of your texts within datasets for future training or fine-tuning of commercial models by big tech companies.
- Allow AI Input & AI Training: This grants extended and permanent authorization to leverage your editorial content for any purpose, including mass scraping for dataset creation and commercial model training.
TDM Policy URL
This optional parameter complies with the regulatory framework of the EU AI Act and the European Copyright Directive (CDSM), allowing you to attach a URL to your network responses to formally indicate content usage terms and conditions to crawlers.
For this preference to be correctly interpreted by automated systems, the policy file must be structured in a machine-readable format following the ODRL profile standard described in the official W3C specification.
You can refer to the official guidelines and code examples by consulting the documentation in the W3C TDM Policy Specification. This is the ideal tool for organizations looking to negotiate licensing agreements or provide their legal contacts to commercial bots.
Link directives for Markdown
Control how AI agents process hyperlinks discovered within the Markdown payload.
- Follow: Allows LLMs to follow links to delve deeper into the topic, discover new resources, and correctly cite your sources.
- Nofollow: Instructs bots to ignore links, preventing further scanning from that page to protect your link network.
Naturally, any existing restrictions on the original HTML page are respected. If a nofollow directive is present on the HTML page, it will be replicated in the Markdown version of the content, regardless of this option's settings.
.well-known/tdmrep.json endpoint
By default, Crusco Agentic Content applies AI policy rules on content usage only to HTML pages and their Markdown equivalents.
However, if you enable this option, these rules will also be written to the .well-known/tdmrep.json endpoint, indicating to the AI systems that the restrictions on the use of your content are global and also apply to all static files, such as images, videos, fonts and PDFs.
Creating perfect Markdown
Crusco Agentic Content automatically generates Markdown from HTML pages out of the box using default settings.
However, every website is unique due to its specific structure, CSS, frameworks, and installed extensions. To achieve flawless, clean Markdown that eliminates AI hallucinations and turns your text into the ultimate content for AI agents, you need to fine-tune the details.
That is why Crusco Agentic Content gives you full control over the content served to Large Language Models.
Content Extraction Modes
Serving LLMs with content that is free of "background noise", such as various layout elements, is crucial both for saving tokens and preventing potential AI hallucinations.
Crusco Agentic Content offers three methods for content extraction:
- Main Content Area: Only the content within the Joomla Component Area is extracted. This is the default option and the one that delivers the cleanest results on most websites.
- Custom CSS Selector: You specify the single wrapper block containing the content to be isolated and converted into Markdown.
- Full HTML Page: The entire document is processed, including menus, with the option to exclude layout tags (header, aside, footer, dialog).
Options 2 and 3 are your lifesaver if your website uses extensions that bypass the Joomla Component Area, which can happen with certain Page Builders. In this case, isolating the wrapper or processing the entire document is the only way to generate a Markdown output that is consistent with the HTML content.
In both scenarios, Crusco Agentic Content allows you to fine-tune the process to always generate a tailored Markdown, optionally removing HTML5 layout tags and entire blocks with specific classes or IDs.
H1 Fallback
The presence of the <h1> tag in HTML documents is crucial for both document structure and SEO ranking.
During Markdown conversion, this importance is inherited by GEO and AEO. The <h1> tag will become Heading 1 (#) in the Markdown file, or, if Front Matter is enabled, its title field. If this primary tag is missing from the HTML page body, the corresponding Markdown will lack identity.
To prevent this issue, Crusco Agentic Content provides two options to search for and select a fallback <h1> tag:
- Scan page positions, then use the
<title>tag.On many sites, the
<h1>tag is not placed directly within the article body but in a different template position (e.g.,banner,top,above component). For instance, on the Crusco HTML website, it is placed inside a module in thebannerposition to leverage full-width layouts and apply specific visual stylesBy choosing this option, the fallback will first be searched across all template positions on the page. If it cannot be found there either, the system will use the
<title>tag, which is guaranteed to be present. - Use the
<title>tag directly.With this option, you are specifying: “No searching elsewhere. If it's not in the page body, it was simply omitted. Use the <title> tag and we are set!”
Create Anchors
Anchors are used for in-page navigation. If you have a page with multiple sections and a TOC (Table of Contents), you likely use anchors to jump quickly from one section to another.
In HTML, anchors can be attached to any element featuring an id. In Markdown, the situation is more complex, as different platforms may handle anchors differently.
In our case, since we cannot know beforehand which model will process the Markdown or which anchor standard it adopts, we must rely on the matrix from the article Markdown Anchor Links: Complete Guide to In-Page Navigation and use the most universal approach possible.
Don't worry. If you enable the “Create anchors” option, you can keep using HTML anchors just as you always have... Crusco Agentic Content will take care of converting them into a cross-platform Markdown version!
Process media tags
Markdown does not have a native syntax for <video> and <audio> tags. Because of this, just like with anchors, different platforms handle them differently.
If you enable this option, multimedia tags are converted into Thumbnail Links, a cross-platform Markdown representation that is ideal for AI.
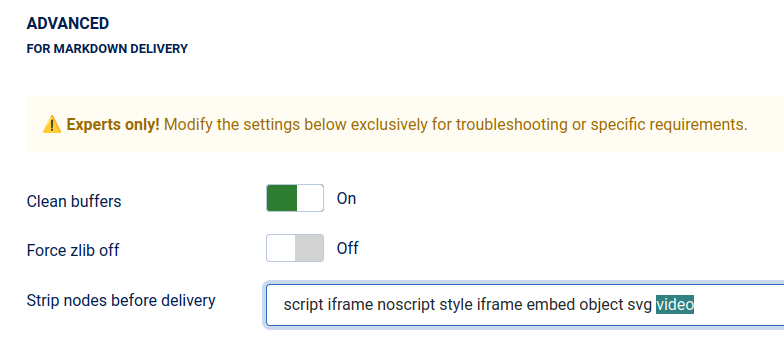
If you leave this option disabled and your HTML pages contain a video tag, for example, unwanted fallback text like “Your browser does not support the video tag” might end up in the Markdown. If you are not interested in converting videos to Markdown but still want to avoid this clutter, you can modify the “Remove nodes before delivery” option by adding “video” to the default list:
Process map tags
The goal of Crusco Agentic Content is to improve the citation rate of your content within AI responses, and it does so relentlessly.
Although <map> and <area> tags have no direct equivalent in Markdown, enabling this option allows the plugin to process them within your HTML pages. It transforms image maps into a semantic, structured text block, a tailored Markdown representation that language models will ingest to understand the image map and boost their overall comprehension.
Strip Base64 images
While traditional search engines tolerate Base64 images (those embedded directly into the code) without any issues, modern Artificial Intelligence systems react differently. When you transform a webpage into a Markdown file to serve it to an AI, the presence of embedded images creates three immediate problems:
- AI Blindness: The image disappears.
AI models look for standard URLs to trigger their visual pipeline. Since Base64 syntax is not automatically decoded in Markdown. The AI does not “see” the image; instead, it only perceives a corrupted text block and ignores the visual content.
- Token Waste: Background noise.
Markdown is designed to save tokens by isolating raw text. A single Base64 image injects up to 80,000 junk text tokens into the file. This overhead saturates the model's memory (context window) and distorts the attention mechanism, leading to inaccurate answers or hallucinations.
- RAG Breakdown: Corrupted vector databases.
RAG systems break Markdown down into small fragments (chunks) for indexing. Base64 fills dozens of these blocks with alphanumeric strings lacking semantic meaning. This pollutes embeddings and the database, causing the bot to return broken code to users.
Enabling the “Strip Base64 images” option fixes these problems at the root: Crusco Agentic Content will automatically strip embedded images from the HTML before converting your content into Markdown.
Remove hidden elements
While hidden content in HTML can be useful for managing user interaction, it only increases the file payload in Markdown. AI bots read all text indiscriminately, consuming unnecessary tokens.
By enabling “Remove hidden elements”, Crusco Agentic Content deletes all elements concealed via inline CSS styles (display: none, opacity: 0, visibility: hidden etc.), ensuring a leaner and more optimized Markdown file.
Remove elements by CSS selector
By default, Crusco Agentic Content automatically removes standard structural elements of the page, such as headers and footers, thereby isolating the core content.
In addition, this option allows you to eliminate custom elements. By entering the respective CSS selectors, you can clean up the layout by removing Joomla modules, third-party extensions, or elements that add no value to the Markdown file, such as cookie banners, captcha systems, comment boxes or print icons.
It is also the ideal tool for eliminating redundant data, such as the author box: since Crusco Agentic Content already includes all author details (bio, photo and social links) in a structured format within the YAML Front Matter, you can use the selector to remove them from the text body. This avoids duplication and serves a lighter Markdown file to LLMs.
Append Raw JSON-LD block
Enable this option only if you truly need every single piece of data contained within the schema markup, even at the cost of less effective content optimization for the AI.
Conversely, you can leave it disabled if you have enabled YAML Front Matter. It already contains a curated selection of the most important metadata, is digested natively by LLMs, and guarantees significantly higher efficiency.
Ignore components
You may not need to enable Markdown for every single section of your website. Typical examples include login and registration pages, or pages generated by components that do not follow Joomla standards, which could turn out to be meaningless (or even detrimental) in Markdown format.
Through this option, you can easily specify which components to exclude.
Viewing Markdown served to AI
You have three ways to check if the Markdown is being generated correctly:“markdown” parameter on the URL
Add the parameter markdown=1 to any HTML page address on your website.
https://yoursite.com/your-page-url?markdown=1
This method works regardless of the enabled delivery method (Content Negotiation or Markdown alternate), unless you are attempting to view the Markdown for an excluded component. In that case, you will receive a 404 error.
curl to simulate an AI bot's Markdown request
If you have enabled “Content Negotiation” and have curl installed on your device, you can use it to force a request for the Markdown format:
curl -si -LH "Accept: text/markdown" https://yoursite.com/your-page-url
This allows you to view both the HTTP headers and the Markdown output.
Markdown mirror .md
If you have enabled the “Markdown mirror .md” option in the plugin settings, you can view the Markdown using the mirror URL.
You can find it by viewing the source code or the HTTP headers of your HTML page via the Network Inspector of any browser. It looks like this:
<link href="https://yoursite.com/your-page-url.md" rel="alternate" type="text/markdown" data-generator="Crusco Agentic Content Pro">
Simply paste the address into your browser to view the Markdown:
https://yoursite.com/your-page-url.md
Plugin screenshots
Ready to ride the GEO wave and the era of AI search engines?
Eliminate syntactic noise, make your content digestible for AI agents, and secure the traffic of the future!
- AI-friendly Input with lower token consumption
- YAML Front Matter for lightning-fast semantic routing
- Integrated AI Policy to protect your copyright
- Tailor-made Markdown to zero out hallucinations
- Full compatibility with all AI crawlers and models
- Universal integration with any extension, template or page builder
- Translated into